SOC Management
Menu: SOC Management (top of the sidebar) Best for: SOC managers, team leads, admins — and analysts, for their own figures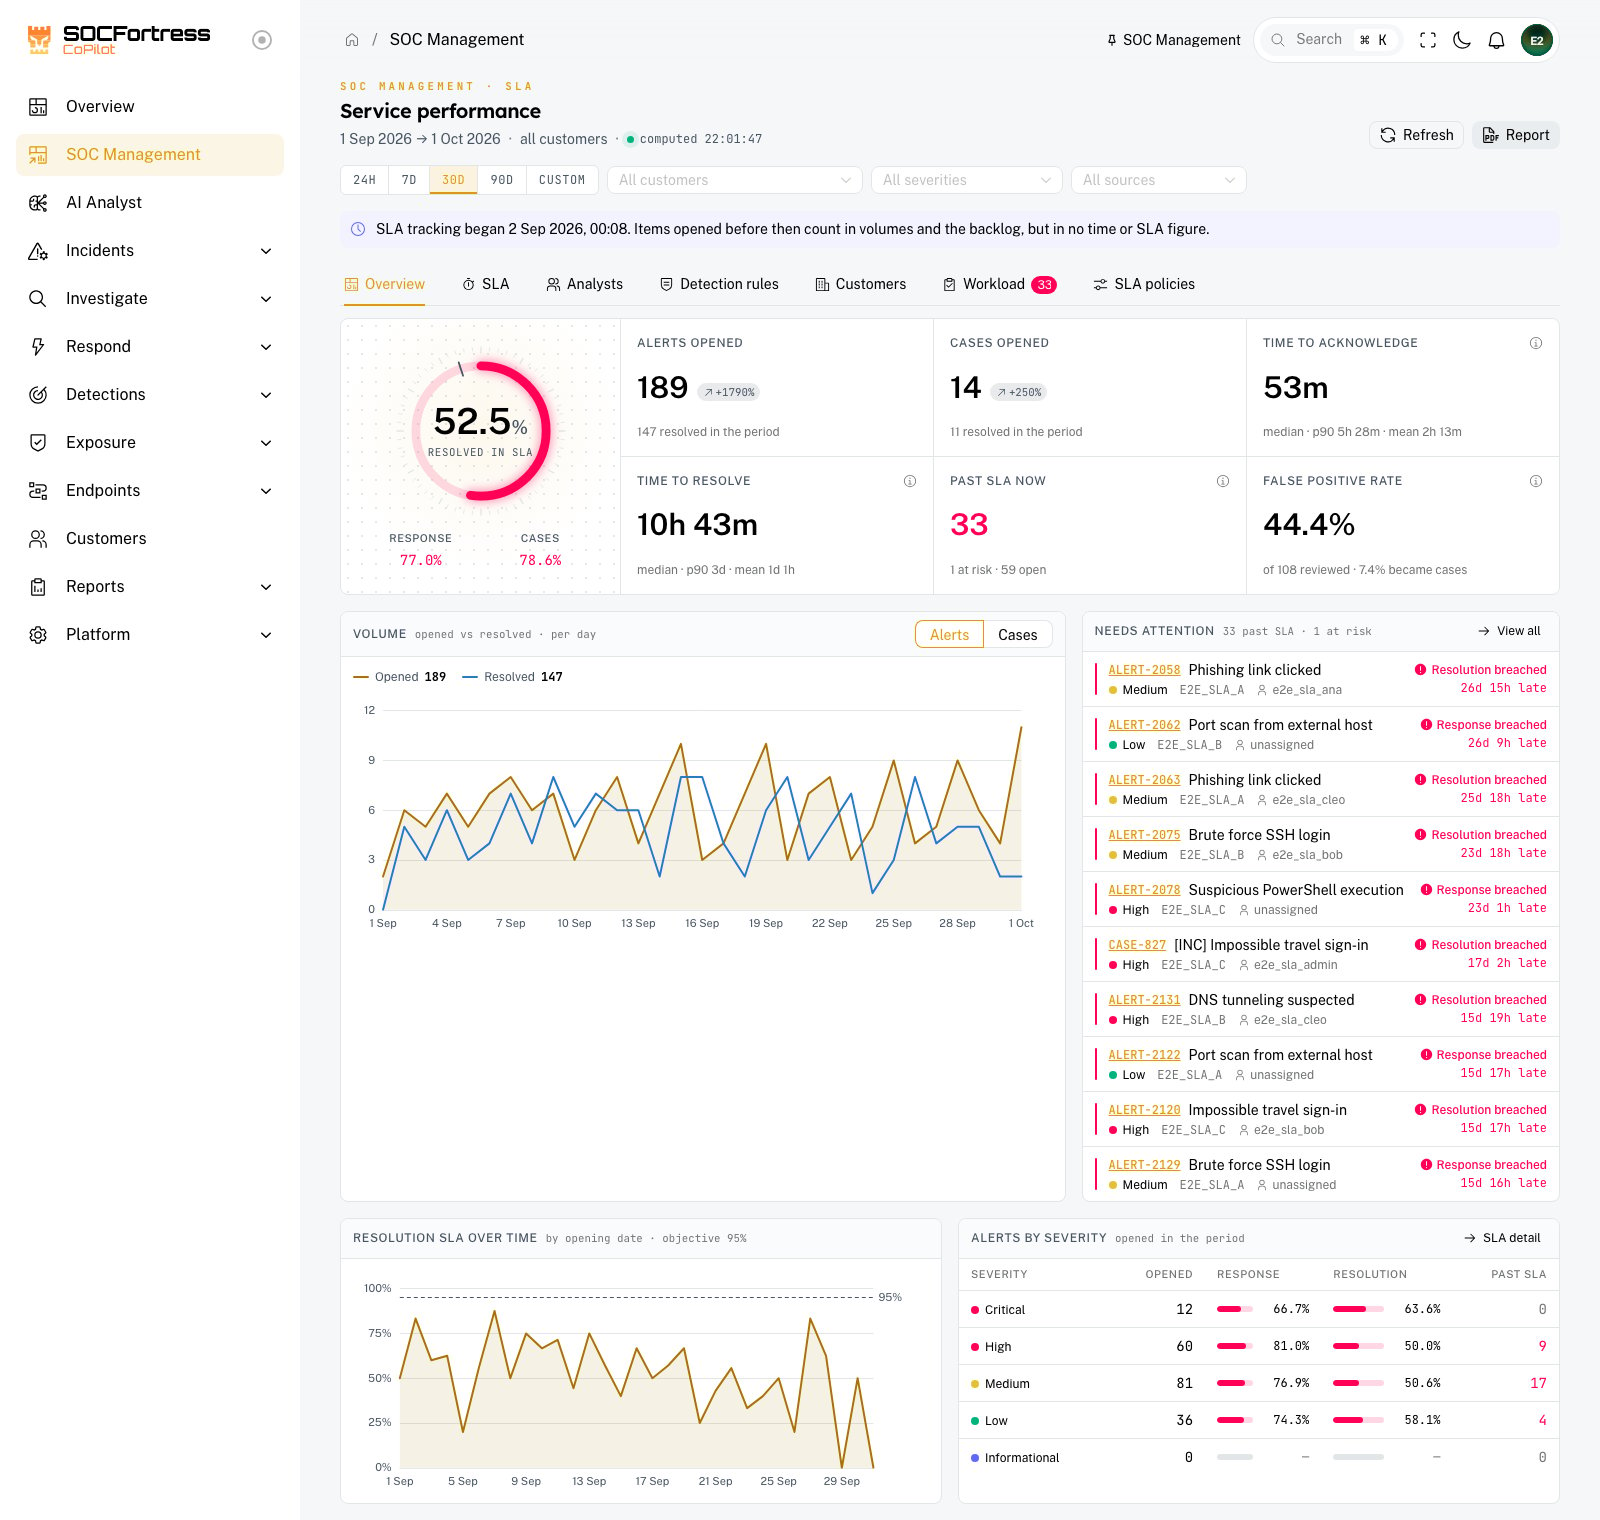
The two clocks
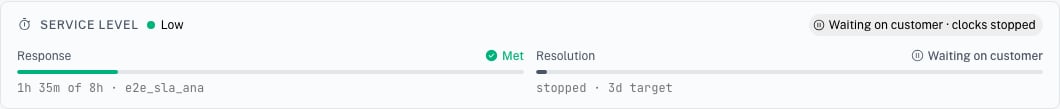
Every alert and case runs two clocks from the moment it reaches CoPilot:
Two rules that matter when reading the numbers:
- Only the SOC acknowledges. A customer commenting on their own alert in the portal, or automation writing to it, does not stop the response clock — the clock measures your response. A customer closing an item does resolve it; those closures are reported apart.
- Waiting on the customer stops both clocks. Set an alert or case to Waiting on customer when you need something from them (a confirmation, a log, a decision). The clocks stop until the item moves on — the customer’s reply in the portal hands it back to you automatically (it returns to In progress). The wait is never counted against the SOC.
How the figures are computed
- Compliance = met ÷ (met + breached). Items still running have no outcome yet and are left out of both sides. “No outcome yet” shows as —, never as 0% or 100%.
- Times are medians. One bulk close of old noise can move an average by days; the median does not. The mean and the 90th percentile are shown next to it for the tail.
- “Past SLA now” counts open items whose clock has run out and is still running. A late acknowledgement stays a breach in the compliance figures, but it is not something to chase anymore.
- Every tab is one snapshot. All tabs, the attention list and the PDF report are computed together, so they never disagree.
- Items opened before SLA tracking began (the upgrade that introduced this page) count in volumes and in the backlog, but in no time or compliance figure — a banner says from when tracking runs.
Filters
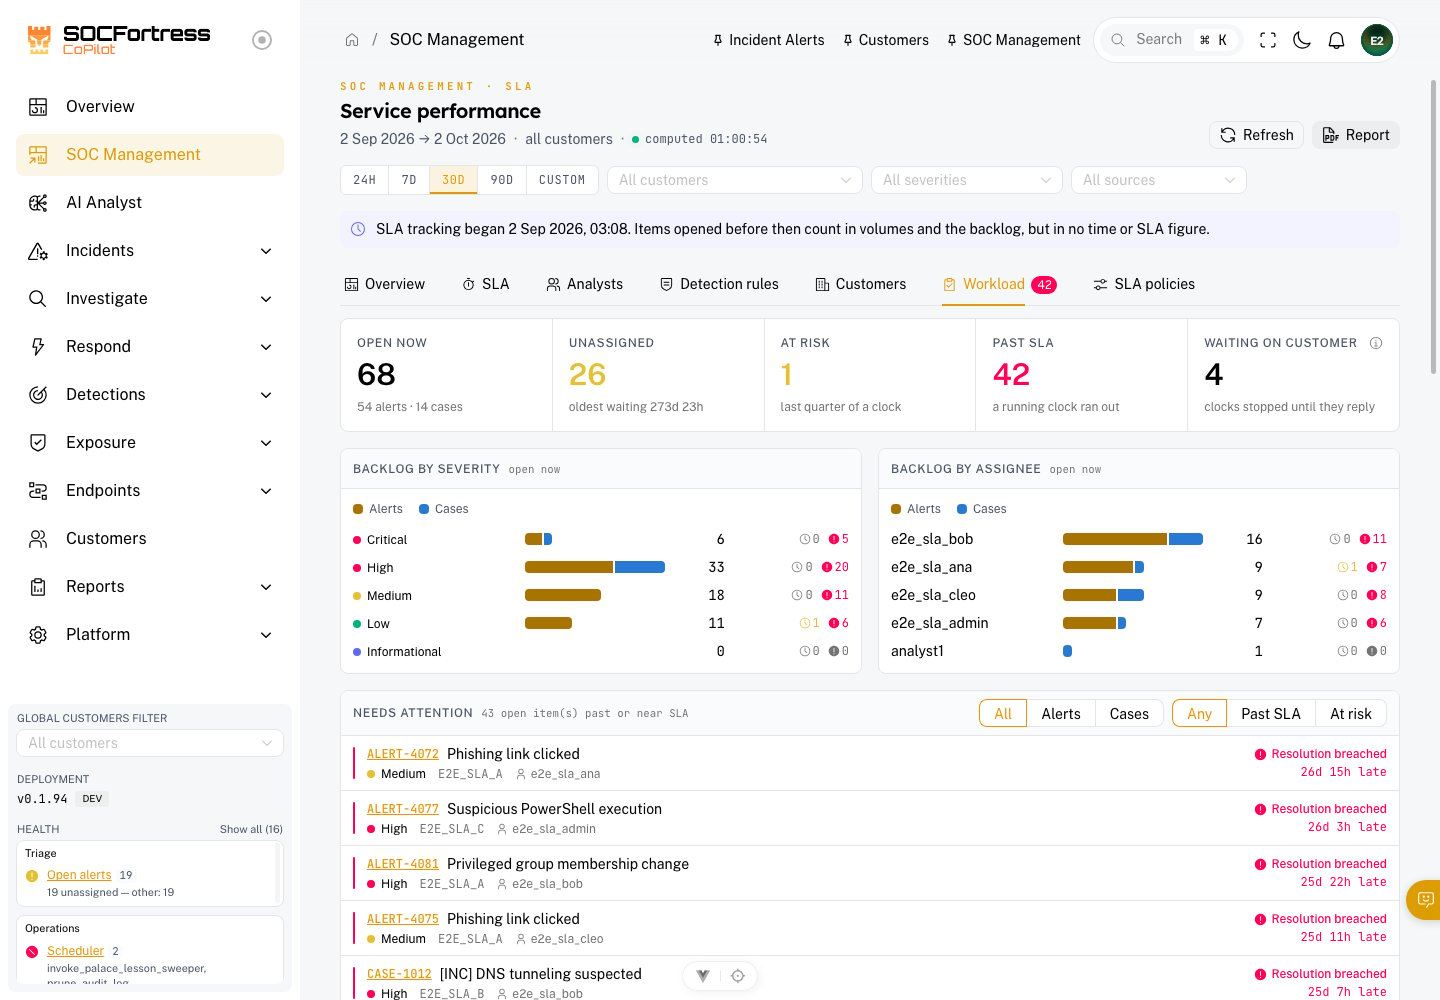
At the top: the period (24 hours, 7, 30 or 90 days, or a custom range), customers, severities and sources. Filters and the current tab live in the URL, so a link you share opens the same view. You only ever see what your access allows: customer assignments and tag-based access apply exactly as in the alert and case lists.Tabs
The PDF report
Report (top right) downloads the SOC operations report for the current filters: the same figures as the page, ready to share with management. SLA figures can also go to a customer, in two ways the SOC controls:- the Service Level Performance section of a customer incident report (Customers → (customer) → Reporting, option SLA performance) — never with analyst names;
- the customer’s own Service Levels page in the Customer Portal, switched on per customer — see Customer Portal — Service Levels.
Being told before it is too late
Two notification triggers, An alert or case SLA is at risk and An alert or case SLA is breached, send a message once per clock to an internal route (Teams, email to the assignee, a webhook…). See Notifications.Related pages
- SLA policies and business hours: ./sla-policies.md
- Incident Alerts: ./incident-alerts.md
- Incident Cases: ./incident-cases.md
- Notifications: ./notifications.md
- Customer Portal — Service Levels: ./customer-portal-service-levels.md